Tools · Personal research tool
Undertow
An experiment in hearing a shift in public language before it becomes the headline. We plan to test it in the open. It hasn’t earned your trust yet.
October 12, 2026 was the target for first unscored alerts; the start is unverified here. October 19 remains the recorded target for scored alerts, not a confirmed milestone. No forward-test results are published here.
Read the method and scorecardWhat it is
Undertow is designed to look for shifts in public writing: new phrases, changes in tone, and the same idea appearing in places that don’t usually agree.
The bet is that some shifts may appear weeks before a topic reaches the front page. That’s a hypothesis, not a demonstrated capability. The proposed test is how we find out.
Why build it in public
A useful test needs more than a list of wins. The plan is to publish confirmed flags, misses and false alarms. Core test rules stay fixed, and permitted human-review changes are recorded.
If Undertow turns out to be noise, the verdict should say so. It is an experiment, not a proven forecasting system.
Intended flow, not results
How it works
- Step 1
Selected public sources
A selected mix of public feeds and open data. Permissions and retention are under continuing review.
- Step 2
Source collection
Public items from the selected sources are collected for analysis.
- Step 3
Language-shift detection
Designed to look for new and rising phrases and ideas spreading across sources.
- Step 4
Weekly flags
Flags are recorded weekly with the time they were raised.
- Step 5
Scored outcome review
Each scored alert gets a sixty-day outcome window before it is counted.
Core test rules stay fixed. Permitted human-review changes are logged, so they can be told apart from what the frozen rules flagged on their own.
Real pixels, historical view
Inside Undertow
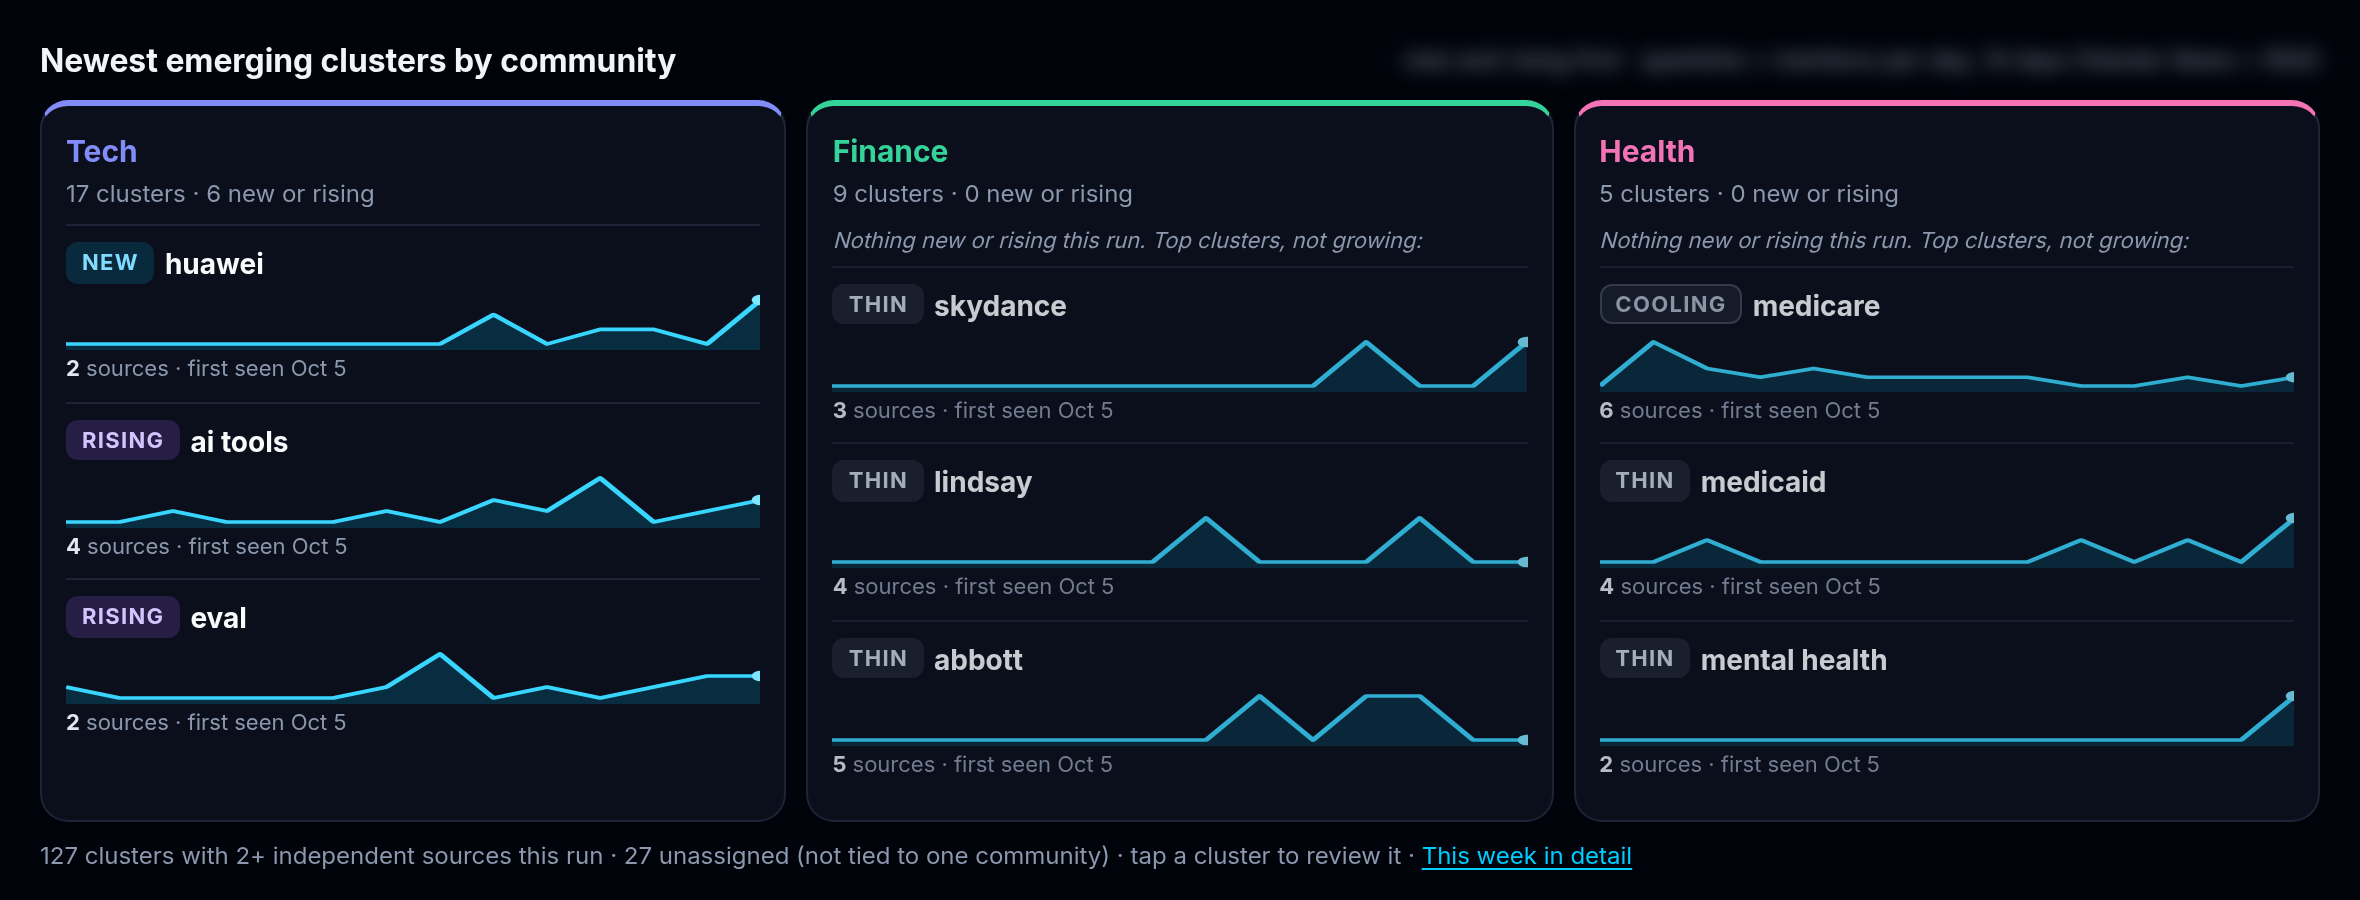
Undertow runs privately. This is a trimmed view from a run before the forward test: newly emerging topic clusters in three of its communities, with two weeks of mentions per day. It is not a forward-test result.

The proposed test
How we’ll judge it
- 01
Rules frozen first
Core test rules stay fixed. Permitted human-review changes are recorded. The fingerprint below identifies the recorded rules definition, not proof that the test has run.
- 02
Weekly, timestamped flags
Record each flag and when it was raised. October 12, 2026 was the target for first unscored alerts; the start is unverified here. October 19 remains the recorded target for scored alerts.
- 03
Checked against reality
Compare flags with later observations after their outcomes have time to mature. How those observations are linked to a flag is part of the method still under review.
- 04
Results before a verdict
A proposed twelve-week observation period is followed by outcome review. Each alert has a sixty-day outcome window, so a final verdict cannot be promised at week twelve. The results will inform whether to keep it, change it or shelve it.
Illustration
What a flag looks like
A simplified picture of the idea: a term rising clearly above its own usual range. The frozen test rules are more specific than this sketch.
Results must earn the verdict
Scorecard
- Weeks complete of 12
- —
- Early flags confirmed
- —
- Misses
- —
- False alarms
- —
No forward-test results are published here. The test start is unverified here. Dashes mean unmeasured, not zero. The twelve-week observation window is proposed; counts will appear as reviewed outcomes become available, misses and false alarms included.
Recorded rules fingerprint
695a8b6ee78aae791aa3d7e899e422e7d53c55c77e1637de2b5e783456af6ac5
This identifies the rules definition. It does not establish a deployed test or a completed result.
Last scorecard update: no results published
Plans, not completed milestones
Roadmap
Fall 2026
Foundation
Checks continueFoundation in place; reliability and recovery checks continue. Source permissions and retention remain under review.
Fall 2026
Forward test
Start unverifiedA proposed twelve-week observation period under fixed core rules. The historical October 12 target does not establish a completed start. Record permitted human-review changes and allow outcomes time to mature.
Winter 2026
Deeper data, smarter reading
PlannedExplore broader coverage and ways to read tone and convergence alongside the test, without replacing its frozen rules.
Winter 2026–27
Public verdict
Contingent decision gatePublish the scorecard and assess the results after outcomes mature. Timing depends on the test and the unresolved method checks; a useful result has to survive the misses and false alarms too.
Later, if earned
Wider use
ConditionalConsider a public tool or a regular brief only if the results justify it. There is no product for sale or release commitment.
Sources
A selected mix of public feeds and open data is the intended input.
Source permissions and retention are under continuing review. No verified source count or blanket terms-clearance claim is published here.
What it is not
- Not financial, investment or legal advice.
- Not a trading signal or a crystal ball.
- Not a product for sale. It is a personal research experiment.
Other tools
RADAR
AI platform changes, explained, with corrections
Explore RADAR Public alphaCCP Study Lab
Learn to investigate a security claim
Explore CCP Study Lab PrototypePROBE
Adversarial AI testing, step by step
Explore PROBEDiscuss the evidence you need.
The same discipline behind these tools, applied to your systems.